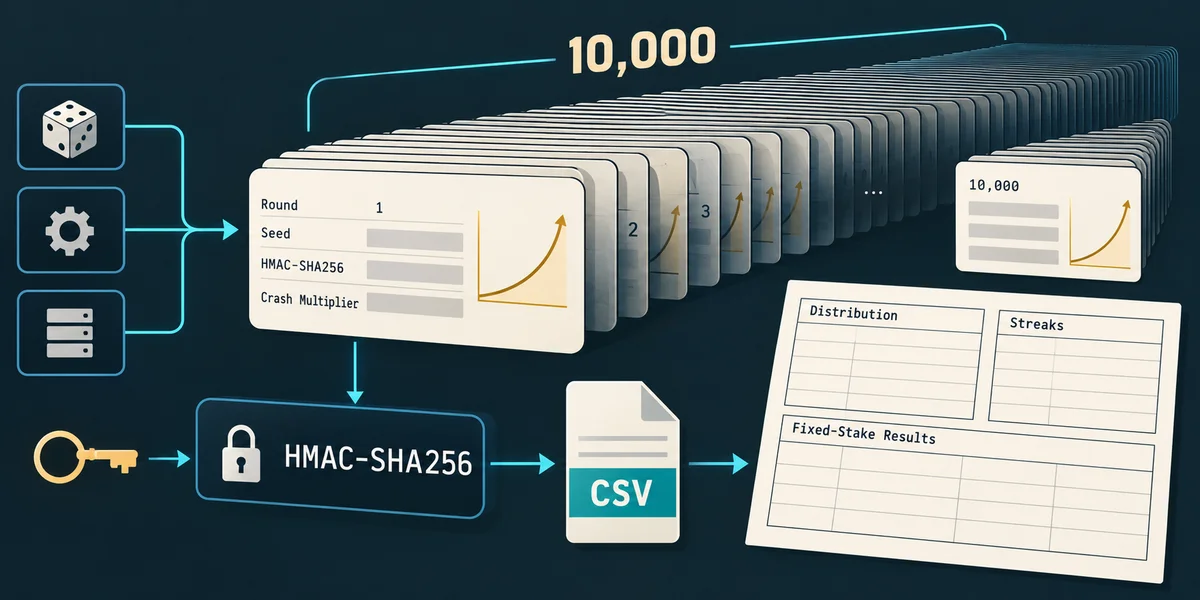


This report describes a public file of 10,000 simulated crash multipliers. The rows were generated from public seed text and sequential nonces using HMAC-SHA256. They were not captured from Aviator, Lucky Jet, Stake or any other casino. The file contains no timestamps, player wagers, cashout requests or payment records. Those limits determine which questions the analysis can answer.
A useful dataset report should let a reader reproduce every displayed number. Here the distribution, streak lengths and fixed-stake ledgers all come from the same CSV. Recomputing a stored hash checks consistency with the declared inputs. It does not turn synthetic rows into real observations or certify a commercial game. The separate Aviator calculator uses SHA-512 and four seeds, so this HMAC dataset must not be described as an Aviator round audit.
1. What the file contains and how to reproduce it
The six columns are round_id, server_seed, client_seed, nonce, hmac_sha256 and multiplier. There are 10,000 data rows. The same public server and client seed text is used throughout, with nonces from 1 to 10,000. Preserve the original row order when calculating streaks or autocorrelation. Sorting by multiplier answers a different question and destroys that sequence information.
For each row, compute HMAC-SHA256 with the server seed as key and the exact UTF-8 message client_seed + ':' + nonce. Parse the first 13 hexadecimal characters as the integer I and set u = I / 2^52. The dataset mapping is max(1, floor(97 / (1-u)) / 100). There is no extra modulo-33 instant-loss test in this generator. Adding one would create a different dataset model and compound the reduction in return.
All 10,000 stored digests match this recomputation, and all 10,000 multipliers match the stated mapping. This is a reproducibility result for the supplied file. Because the seeds are already public, it says nothing about keeping a future casino result secret. The dataset README, machine-readable summary and Python reference let you repeat the checks without placing a bet.
2. Summary statistics: a median is not a cashout return
| Metric | Value |
|---|---|
| Rows | 10000 |
| Reproduced HMAC digests | 10000 |
| Results at 1.00x | 396 (3.96%) |
| Median | 1.88x |
| Arithmetic mean | 7.27652x |
| Maximum | 4109.28x |
| Results ≥ 2x | 4711 |
| Results ≥ 10x | 982 |
| Results ≥ 100x | 81 |
The median is 1.88x: half the ordered observations lie on each side of the middle pair. The arithmetic mean is 7.27652x, pulled upward by occasional large values. Neither statistic means a player can routinely cash out at that multiplier. A fixed-target bet pays only when the round reaches its target, and its return must include every losing stake.
The largest recorded value is 4,109.28x at row 3,844. It is one observation in this synthetic sequence, not a reported casino payout or the maximum permitted by an operator. A large multiplier also does not show what stake was allowed or whether a payment cap applied. Those fields are absent. Distinguish the distribution of displayed multipliers, the distribution of a particular bet's net result and the movement of a funded balance.
Heavy tails explain why the mean is unstable across finite samples. An ideal unbounded continuous tail and a finite 52-bit implementation are not the same mathematical object. Real games may impose further caps. There is no reason to describe this finite file's mean as an infinite theoretical payment or to promise that another 10,000-row sample will have the same maximum.
3. Nine disjoint multiplier bands
| Multiplier band | Rows | Share |
|---|---|---|
| 1.00x | 396 | 3.96% |
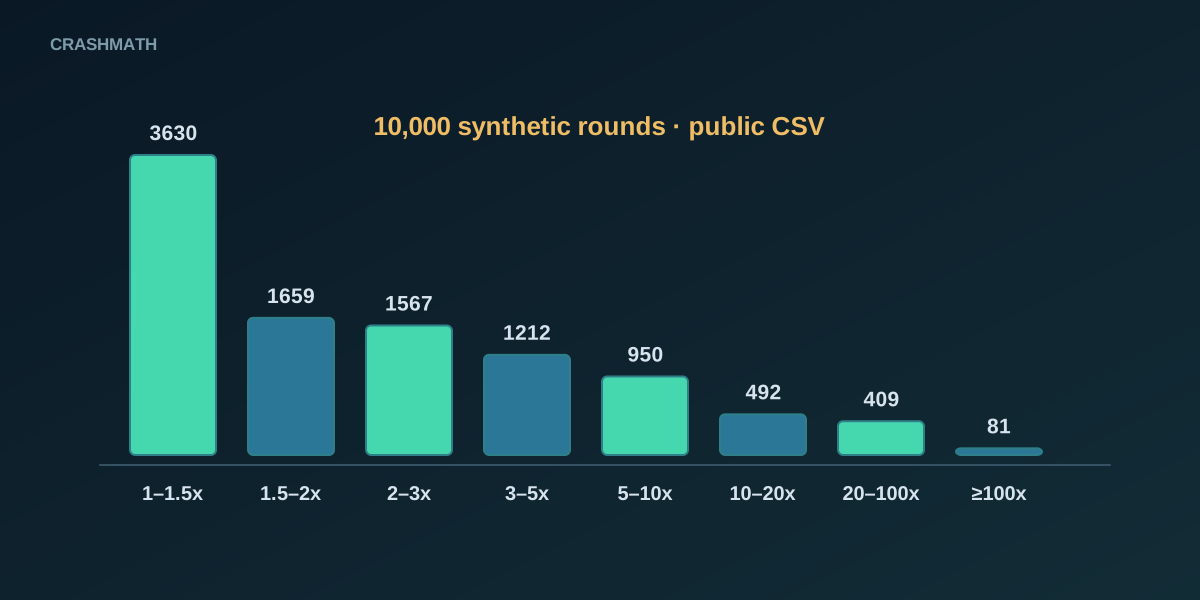
| 1.01-1.49x | 3234 | 32.34% |
| 1.50-1.99x | 1659 | 16.59% |
| 2.00-2.99x | 1567 | 15.67% |
| 3.00-4.99x | 1212 | 12.12% |
| 5.00-9.99x | 950 | 9.50% |
| 10.00-49.99x | 817 | 8.17% |
| 50.00-99.99x | 84 | 0.84% |
| 100+x | 81 | 0.81% |
These nine bands contain exactly 10,000 rows and 100% of the sample. Lower endpoints are included; the next band's lower endpoint is excluded. Thus 1.50x belongs to the 1.50–1.99 band, while 2.00x belongs to 2.00–2.99. The first band contains only the displayed 1.00x value. Defining endpoints matters when comparing a histogram with fixed-target hit counts.
There are 396 results at 1.00x, or 3.96%. This is not an estimate of a separate 3% modulo mechanism. Under the rounded mapping, all unrounded values below 1.01 become 1.00 after flooring and the lower clamp. For an ideal uniform u, that interval has probability 1 - 0.97/1.01 = 4/101, approximately 3.960396%. The observed count happens to be close to that model expectation; equality is not required in every sample.
A goodness-of-fit calculation must use this discrete, rounded model and a clearly specified test. Comparing it with an unrounded continuous CDF at its 1.00x atom can produce a misleading result. We do not publish a new chi-square p-value here. In any case, failure to reject a distributional null would not prove secure seeds, a valid pre-round commitment or absence of operator manipulation.
4. What the recorded streaks show
| Streak definition | Longest run, rows |
|---|---|
| Below 2x | 13 |
| At least 2x | 12 |
| Exactly 1.00x | 2 |
| Below 10x | 79 |
At a 2.00x target, a loss means a stored multiplier below 2.00x; equality counts as a hit in this ledger. The longest such losing streak is 13 rows. The longest winning streak at that target is 12. The longest run of displayed 1.00x values is two, and the longest interval without a 10x result is 79 rows. Each maximum depends on the chosen definition, sequence length and this particular seed sequence.
The chance of losing the next m independent bets is q^m when q is the specified loss probability. That is different from the chance of encountering at least one such run anywhere in 10,000 bets: overlapping windows share observations. It is also different from the expected longest run. Treating all three quantities as interchangeable produces exaggerated confidence about bankroll survival.
As a separate arithmetic illustration, doubling from one unit after each loss costs 1 + 2 + ... + 4,096 = 8,191 units over 13 consecutive losses. A 1,000-unit bank cannot finance that sequence. A funded simulation must stop before an unaffordable next stake, or explicitly define a smaller final stake. The existence of this run in one file does not establish the exact bankruptcy round for every Martingale session.
5. Fixed one-unit bets on the same sequence
The following ledgers begin with 1,000 units, stake exactly one unit each row and use a target selected before the sequence starts. A hit returns the stake plus k-1 units of net profit; a miss loses one unit. Every next stake remains funded in these five ledgers. No fees, bonuses, timing errors or operator limits are modelled. Units are accounting units, not observed dollars or customer balances.
| Target | Wins | Net, units | Final bank | Minimum bank |
|---|---|---|---|---|
| 1.50x | 6370 | -445.00 | 555.00 | 543.00 |
| 2.00x | 4711 | -578.00 | 422.00 | 407.00 |
| 3.00x | 3144 | -568.00 | 432.00 | 390.00 |
| 5.00x | 1932 | -340.00 | 660.00 | 586.00 |
| 10.00x | 982 | -180.00 | 820.00 | 626.00 |
For example, the 2x ledger has 4,711 wins and 5,289 losses. Its net result is 4,711 × 1 - 5,289 = -578 units, leaving 422 from the initial 1,000. The lowest balance reached is 407 units. That minimum is not maximum drawdown, which measures the largest fall from a prior peak. Reporting one as the other would misdescribe the path.
All five targets lose in this particular file, but the losses do not equal exactly 3% of turnover. With 10,000 one-unit bets, the ideal model expectation is -300 units, while realized results vary. The 10x target happens to lose less here than 1.5x. Selecting 10x after seeing the table would be selection on past outcomes, not evidence that its future expectation is better. Different targets also share the same round sequence, so these are not five independent experiments.
6. Autocorrelation is descriptive evidence
| Lag | Sample coefficient |
|---|---|
| 1 | -0.00106853 |
| 2 | -0.00255805 |
| 3 | -0.00223775 |
| 5 | -0.00177960 |
| 10 | -0.00354494 |
The displayed coefficients use the raw multipliers, their sample mean and the denominator formed from all 10,000 squared deviations. Values are rounded to eight decimal places. They are small for the listed lags, but a small sample coefficient is not proof of exact independence. Heavy tails, alternative transformations and the selection of lags affect how a diagnostic should be interpreted.
We do not attach a universal ±1.96/√N confidence rule to these heavy-tailed raw values or claim that a hash's avalanche property proves statistical independence. A prediction study would need a rule fixed before testing, untouched future observations, all predictions including misses, and a net-return calculation. Rechecking a public deterministic seed sequence is not an out-of-sample test against a live game's hidden inputs.
7. Why this file cannot test paying hours
A row number and a nonce are counters, not timestamps. The CSV contains no date or clock-time column. It therefore cannot be divided into genuine morning, evening or four-hour UTC observation groups. Assigning artificial times to these rows would manufacture the variable supposedly being tested. There is no measured daily RTP cycle or device-latency comparison in this report.
A real time-of-day study would first define the game version, timezone, collection period, target, stake treatment and missing-round policy. It would need timestamped observations and would distinguish a change in player behaviour from a change in the multiplier process. Even then, a difference in one period would require uncertainty analysis and a future test before supporting a practical claim. None of that evidence can be supplied by renaming the present simulation.
8. Download and interpret the results
Download the original 10,000-row CSV and keep its bytes unchanged. Recompute the hashes first, then the rounded multipliers, then the histogram and chronological ledgers. Check that the band counts sum to the row count and that each target ledger reconciles wins, losses, turnover and final balance. These simple identities catch mistakes that an impressive-looking p-value would not repair.
The Monte Carlo terminal illustrates a different, newly generated random path. Its outcome is not this fixed dataset's ledger. The hash calculator also distinguishes its separate Aviator branch from illustrative HMAC examples. Use a recorded commercial round's own inputs and exact protocol before attempting a real verification. The present results support reproducible mathematical discussion, not predictions, platform certification or a promise of safe play.