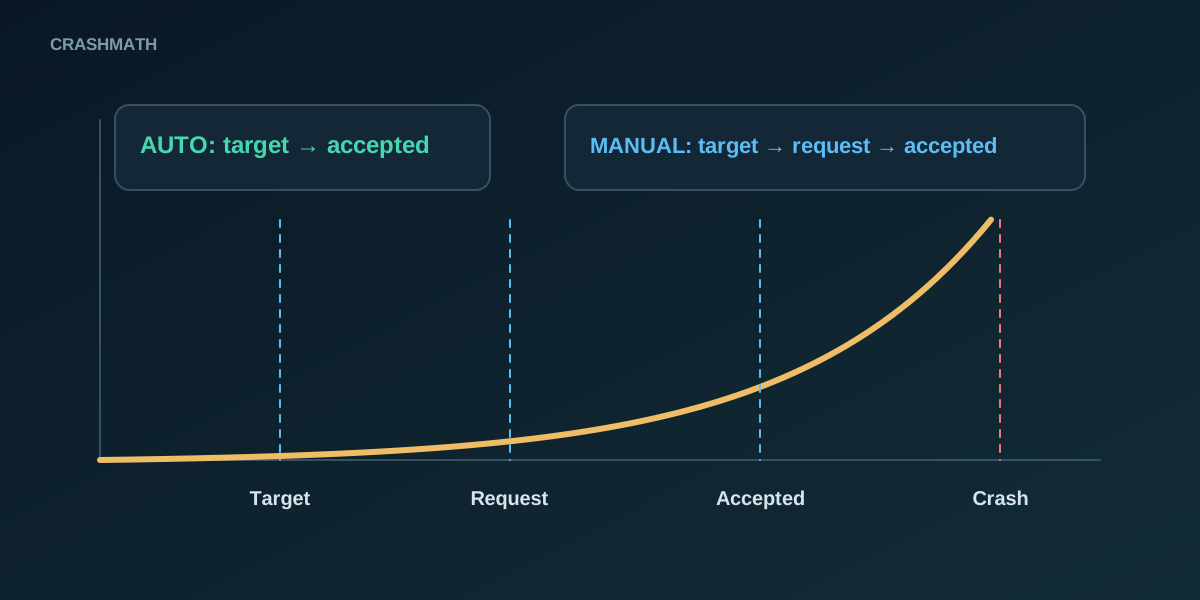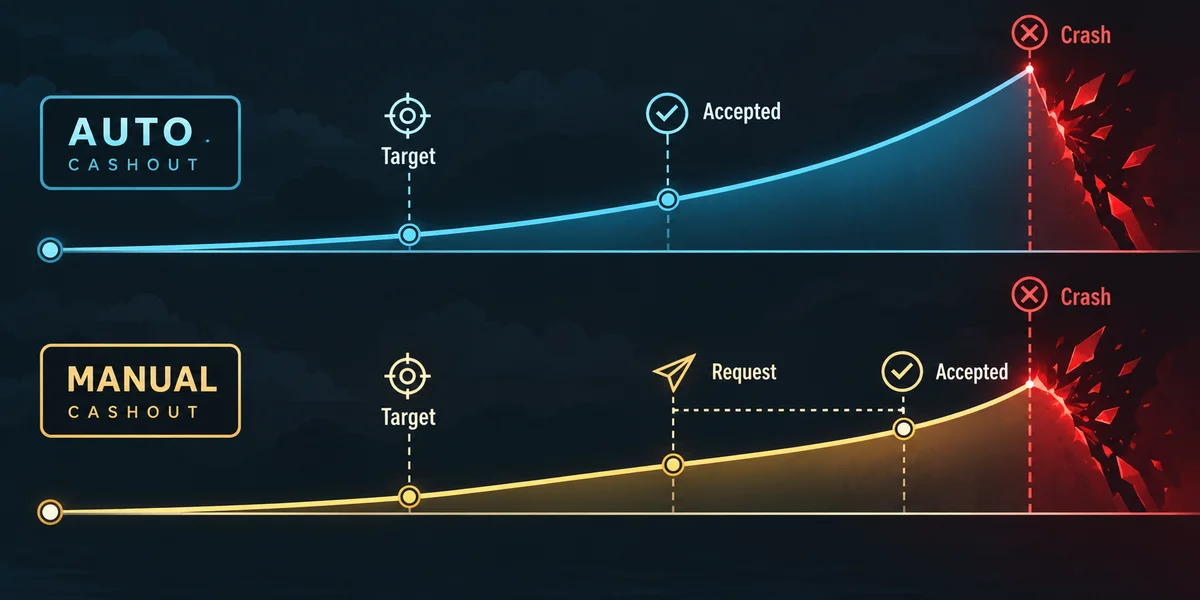


Auto-cashout can make a chosen exit easier to follow. Whether it also improves expected return depends on acceptance and payment rules. “The manual order arrives later” is not enough to calculate a universal financial penalty: does a surviving delayed order pay the old intended target or the higher multiplier when accepted? Those two contracts give different answers even with exactly the same outcome distribution.
Here we derive both answers and replay three explicit rules on the existing public synthetic file. This is not a packet-capture study, a reaction-time experiment or a claim that every provider guarantees server-side execution during a disconnection. The practical benefit of a preset target remains useful, but it must be described separately from a measured return advantage.
The assumptions determine the answer
Use a continuous reciprocal survival law P(M≥x)=0.97/x for targets above 1. Assume a one-unit accepted stake, no fees or caps and equality counted as reaching the target. Let m be the intended cashout and r≥m the fixed multiplier that must be reached before a delayed order is accepted. Treat r as an input, not an observed device measurement. This is a declared educational 3% model, not a universal protocol for Lucky Jet, Aviator or JetX.
With an accepted preset target m paying m, expected net is m×0.97/m-1=-0.03. With delay requiring r but still paying m, expected net becomes m×0.97/r-1. With delay requiring r and paying r, it becomes r×0.97/r-1=-0.03. The lost wins in the interval from m to r are compensated by the higher payment on surviving wins in the last case. This cancellation needs the stated distribution and payout, not merely a claim that manual execution is fast.
The fixed-payment penalty
The unconditional probability of an outcome in the missed interval is 0.97/m-0.97/r. Multiplying by m gives the extra expected loss per unit for the fixed-payment contract. It is not itself the extra loss percentage: one affected outcome changes gross payment by m units. It is also different from the conditional chance of failing after the flight has already reached m, which is 1-m/r under this model.
| Arrival r | P(reach r) | Edge if paid 2 | Extra percentage points | Edge if paid r |
|---|---|---|---|---|
| 2.000 | 48.500000% | 3.000000% | 0.000000 | 3.000000% |
| 2.025 | 47.901235% | 4.197531% | 1.197531 | 3.000000% |
| 2.100 | 46.190476% | 7.619048% | 4.619048 | 3.000000% |
All rows intend m=2. The hypothetical arrival 2.1 has success probability 97/210 and a missed-interval probability of about 2.309524%. Fixed payment 2 adds 4.619048 percentage points, producing 7.619048% total expected loss per unit. Payment at 2.1 retains 3%. At arrival 2.025 the fixed-payment addition is 1.197531 percentage points, not 0.60; total loss is 4.197531%. None of these arrival levels is labelled a desktop or mobile benchmark.
The Latency Calculator explicitly uses the fixed-target payment assumption. Its declared curve maps total delay τ seconds to r=m×exp(0.06τ). At m=2, a rise to 2.1 corresponds to about 0.813169 seconds in that curve, not a measured 350-millisecond universal delay. Input ping and reaction time are hypothetical. Animation, server acceptance, caps, packet loss and actual settlement can require a different model.
A replay anyone can reproduce
Download the existing 10000-round synthetic CSV and cashout_models.py into the same directory. Runpython cashout_models.py or pass the dataset path. The standard-library script verifies the documented file hash, evaluates every multiplier using decimal comparisons and reports gross, net and final balance. It makes no network calls and does not place bets.
Each hypothetical rule starts with 10000 units and stakes one unit per row, so every one of the 10000 wagers can be funded before settlement. The rules are: reach 2 and pay 2, reach 2.1 and pay 2, reach 2.1 and pay 2.1. They use the same rows, count equality as success, charge no additional cost and pay in integer cents. They do not simulate a browser clock or derive arrival 2.1 from measured packets.
| Settlement model | Wins/10000 | Gross units | Net units | Final balance |
|---|---|---|---|---|
| Reach 2, pay 2 | 4711 | 9422.00 | -578.00 | 9422.00 |
| Reach 2.1, pay 2 | 4471 | 8942.00 | -1058.00 | 8942.00 |
| Reach 2.1, pay 2.1 | 4471 | 9389.10 | -610.90 | 9389.10 |
The fixed 2 target wins 4711 times. Both delayed rules win 4471 times. Their net totals are-578.00,-1058.00 and-610.90 units respectively. The compensated replay is not exactly equal to the preset replay on this finite path: equality of population expectation is not equality of realised samples. The public file is a deterministic synthetic reference with public seeds. It does not establish a live provider’s return or predict a private next round.
Independent integer-cent counts and SQL aggregation reproduced the totals. For each rule final balance equals starting balance plus gross payout minus total stake. The difference between delayed rules comes entirely from the payment assigned to their identical winning rows. That controlled comparison is narrower and more reproducible than attributing every difference to human reflexes without order and settlement records.
Check ledger arithmetic before explaining a cause
Consider a separate hypothetical aggregate, not an experiment:1000 one-unit wagers,539 wins paid 1.80 versus 508 wins with mean gross payment 1.8214. The first net is 539×1.80-1000=-29.80. The second is 508×1.8214-1000=-74.7288. Their difference is-44.9288 units. These identities assume that the stated average is exact and omit currency-rounding complications.
Such totals alone cannot establish that 31 missing wins were caused by a 240-millisecond reaction delay, identify which rounds differed or prove that the second order was entitled to payment. A genuine experiment needs round-linked client observation, order submission, server acceptance and actual payment records, with a defined clock and handling of rejected or missing events. No such live experiment is claimed here.
The 7/3 split is conditionally useful
Suppose two accepted bets share one flight:7 units target 1.45 and 3 units target 10. If the first succeeds, it returns 10.15 gross, covering the combined 10-unit stake with 0.15 left over even if the second fails. This is a conditional accounting benefit after success, not free capital before the round. Both stakes are exposed to the same early crash and their outcomes are dependent.
| Final multiplier | Combined net | Model probability |
|---|---|---|
| M <1.45 | -10.00 | 33.103448% |
| 1.45 ≤ M <10 | 0.15 | 57.196552% |
| M ≥10 | 30.15 | 9.700000% |
Below 1.45 the combined loss is 10. Between 1.45 and 10 the net is+0.15; at 10 or above it is+30.15. Under the stated law these outcomes have probabilities about 33.103448%,57.196552% and 9.7%. Weighted net is-0.30 per 10 wagered. A discretionary manual second exit would require its own rule and would change this table. Neither version secures session solvency or makes the first target certain.
What to confirm before relying on a preset
Check whether the target was accepted with the wager, stored server-side and covered by the product’s published disconnection rules. Confirm minimum and maximum targets, equality and payment precision. A preset can remove a last-moment client instruction if implemented that way. It cannot guarantee that an unaccepted setting exists on the server or that every system failure is impossible. A site badge is not a substitute for those records.
Manual execution can involve display age, decision time and delivery time. Their values vary and should not be added from unrelated supposed “typical” benchmarks. A single heartbeat round-trip also does not establish the complete cashout path. A recorded screen may show a state out of time with acceptance, so do not infer a causal ordering from a screenshot alone.
Use automation to enforce a choice, not promise profit
A preset can help someone keep an intended target rather than changing it mid-flight. It does not remove every emotional decision: stake size, target edits, new rounds and chasing remain possible. Set an affordable spending boundary and stop if the next wager cannot be funded. The expected-value guide separates turnover cost from a guaranteed session loss.
This article’s independent value is the explicit payment comparison and reproducible synthetic replay. Repeated wording on another site does not corroborate a study. No counterpart was changed and no search-ranking or sanction conclusion is drawn from overlap. Partner actions remain direct registration choices with no compulsory demo step; they do not prove that a specific implementation has the assumed timing or payout.